A new kind of model is out. It makes decisions instead of writing text, it answers in well under a second, and it costs a hundred times less than the models you are used to. I tried it on everything I am building, and the results are at the bottom of this post. First, some background on why it matters.
Prompt engineering has always been rubbish. I wrote early last year about how it is the punch card era of programming all over again. If AI was so good at writing its own text, why could it not write the prompts as well?
Early in my use of large language models I came across DSPy, which solved a lot of the problems around my laziness with prompts.1 It felt like an important step forward, and it felt like there was a useful product to be built on that idea. So I built my own version, Kaijo. It gave deterministic outputs and improved its own prompts: you gave it feedback, and it wrote the improvement for you. It even used its own system to create prompts for itself, which was both elegant and hard to get working. I ran a waitlist, gained some traction, used it on a few projects, and it was undeniably useful. However, something was always slightly missing.
Months later I worked out what that was. Optimising the prompts is only half the job. The AI also has to work out the structure of how it approaches the work. If I make the early decisions about how to break the job down, I am micromanaging it, and it never gets to find a better way.
Loops, Then Programs
My first step was to replace that structure with a powerful model and a loop, and let it work out the approach for itself. Loops are much simpler to run than any orchestrator, which is why I cut Ralph down to one line with no setup. This was a great start, and the job was normally done to a good standard. But even with the most powerful models there was some variability in the process, and letting the model call tools endlessly to work out what it needed cost a lot of tokens.
The next step is to codify that process. Ask the AI to write a structured, repeatable program which itself calls AI to get certain jobs done. Along the way you give the AI feedback where the structure does not quite work, and build up a set of repeatable cases, or evals, which it uses to check it has not gone off the rails while it makes improvements. I wrote up my latest thinking on this last week, when I explained why prompt evals alone are useless.
This breaks the use of AI into smaller pieces inside a larger program, which is a great way to build in the right amount of reliability. The repeatable parts matter as much as the AI parts. As I put it when I argued that you should stop saving tokens and start writing scripts:
The pattern matching is deterministic, so it lives in the script, where it runs in milliseconds and costs nothing. The judgement is not deterministic, so it stays in the prompt.
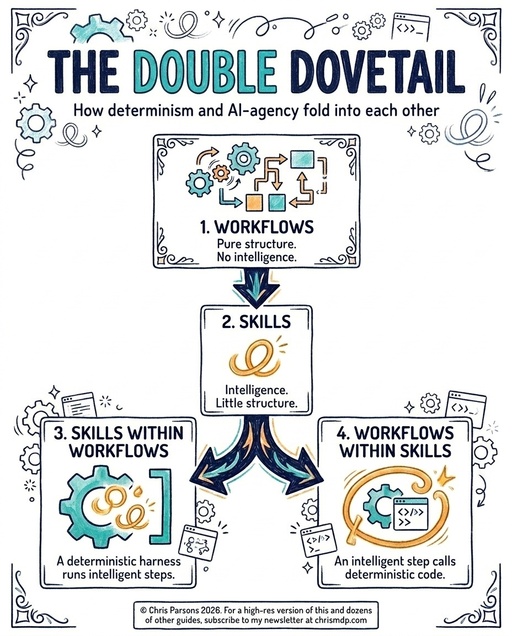 The Double Dovetail, from Stop Saving Tokens. Start Writing Scripts.
That is where some of the other Kaijo properties would be really useful. The self improvement not so much, as you need an agent to consider the whole build, but the single call simplicity, the guarantee that the output was well structured enough for a program to understand it, and the way you could choose a fast model for the job. Often you want a fast routing model at the beginning of the process, for example, as I talked about when I walked through building one for a client in my Make Your AI Rollout Stick webinar.
A Model That Decides but Cannot Talk
This week we got a new type of model with exactly those properties. TypeSafe calls it a System One model, trained with a process it calls Reinforcement Learning for Calibrated Decisions, and the first one is called Jev.2 It can choose between options, give a score against some criteria, or answer yes or no as a probability. It brings nuance to a decision you might previously have hard coded, or paid an expensive LLM to make. It cannot generate text, but it can decide when you need text, so you call a traditional LLM only when you need one. It makes lots of decisions in parallel, it is fast, and it is very cheap: $42 per billion input tokens, with output tokens free.3 That is cheaper than DeepSeek 4.1 Flash on uncached input, with a guarantee that a machine can read every answer, and it answers all your questions at once.4
The guarantee is about the shape of the answer, not its truth. Jev cannot return an option that is not on your list, but it can still pick the wrong one, and the calibrated probability tells you how often that happens across many decisions, not which ones were wrong.5
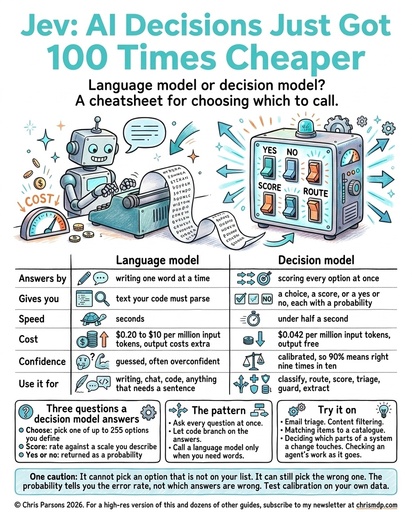 High-res version available to newsletter subscribers
A Barrage of Questions
This is very powerful for systems that mix AI with regular code. We can hit any piece of input with every question that might be relevant, like asking for a whole multiple choice survey to be completed, and then let code act on the results. TypeSafe’s smart home demo shows the pattern. The code asks every question up front: is this a command or a question, which room, which device, which action. It throws away the answers that do not apply, and only hands over to a text generating model when someone needs a sentence back.6
Jev is behind a waitlist for now, but the approach is not exclusive to TypeSafe. Qwen’s open reranker models on Hugging Face already answer a yes or no question with a probability read straight from the model rather than generated as text, and more will follow.7
I Tried It
In the text adventure I am building, a change in the world has to be checked against every subsystem that might care about it, and a decision model can work out which ones need updating and whether an LLM needs to run at all. For my email triage, I can ask a batch of questions about importance, urgency and safety, including who a message concerns, quickly and cheaply, and discard anything that is not relevant before an expensive model ever sees it. For batch jobs like the recipe importer or meal generator at Cherrypick, choosing between a few hundred ingredient types when reading a recipe, and deciding how complex it is to cook, is exactly this shape.
As expected, there are a ton of little places to apply this in the agent builds I am running at the moment, including the successor to my Telegram bots, which is more productionised and which I will talk more about soon. So I tried it. I got Fable to read both codebases, work out from the documentation where a decision model could stand in for a decision an LLM makes today, and run side by side tests against Claude Sonnet 5 and DeepSeek V4.1 Flash using the eval setup I already had in place. Across email triage, the game’s action interpreter, recipe classification, my link reading agent and ten public benchmarks, that added up to around sixteen thousand decisions. Here is what I found.
It is good at closed lists. Sorting ingredient lines into twenty supermarket categories, it agreed with the reference answer 99% of the time, just ahead of Sonnet. It picked the right country from capital, region, languages and currency alone at every size up to the full list of 240, and given a made up list of a thousand shop orders, each with a status, it answered “is this order delivered” for every one of them in a single call, in just over a second, without a single mistake. On the ten public benchmarks it matched DeepSeek Flash and Sonnet 5 within a point or two, and beat both on toxicity. I tried injecting instructions into the input, and it seemed safe. French, German and Japanese scored the same as English. The probabilities are honest. When it is unsure it says so, and when it is confident it is nearly always right. The LLMs claimed near certainty on almost everything, including a fifth of the emails they dismissed that I needed to see. On email triage itself it was about as good as DeepSeek Flash and Sonnet at deciding what needed my attention: it agreed with my current setup three times in four where they managed four in five, and where it disagreed, an independent judge sided with it more often than not. That is useful. It can take the clear two thirds of my inbox in under a second and hand the rest to a bigger model.
It needs tuning and the right questions to make it work. In the game, with one untuned prompt, it called every attack and every persuasion a risky roll, and it asked for clarification far more often than it should. I gave every model one prompt and no tuning round, so treat the game numbers as a first pass. Unsurprisingly, it cannot multiply: “is 17 times 23 more than 400” came out right three times in four, with a bias to no, so do computation in code. Its confidence does not fall when the input is nonsense. I gave it a weather report where a customer complaint should have been and asked whether the customer wanted a refund, a replacement or an explanation, and it picked explanation at 0.99. Again, this was my issue. There was no option for “this is not a complaint”, and it will not invent one, so give it every option it needs to make a good decision, including the one that says the question does not apply. And there are some hard limits: at most 255 options in a choice, ten levels on a score, and about 32,000 tokens of context.
It is still a model. It makes nuanced decisions, it gets some of them wrong, and better models will make better decisions whatever the speed and the price. The important point is that this is the first model of its type. There will be more of them, and more powerful ones, able to make these kinds of decisions far better than this one can. A fair comparison gives each model a couple of rounds of revision before you judge it, and I would expect the game results in particular to move.
On reliability it held at ten requests a second for five minutes with no errors and every answer under a second. At twenty a second it started to fall over, with one request in ten taking eight seconds or more and a handful failing outright. Fine for the jobs I have in mind, and not something I would put a queue of a million items behind today.
I am not going to deploy it just yet, because it is one service and it has been public for a couple of days. I am keeping a very close eye on the technology in general, and when more than one provider offers a model like this, especially somewhere like OpenRouter, I am all for it.
Update, 25 September: That did not take long! Within two days of the launch, six open clones of Jev had appeared, all built from public models because TypeSafe has not released its own.8 This is good news if you are buying rather than building, because a variety of companies producing these models is what keeps you independent of any one vendor. The clones show that the architecture is easy to reproduce, but none of them comes with evidence you can check. Treat every number, from TypeSafe or from a clone, as a claim until you have tested it on your own data.
Decisions Just Got Cheaper
AI engineers need to learn this in detail. Chief executives and their leadership teams need to know that simple AI decisions on large amounts of data potentially got hundreds of times cheaper overnight. That matters for any content filtering, triaging or routing your teams do, whether you thought it was too expensive to hand to AI, or whether people are currently doing it by pasting things into Claude.
Within six to twelve months, once more models are trained this way, this kind of decision model will be in every custom AI product, and you can bet today that the frontier labs are either scrambling to build their own or scrambling to buy TypeSafe.
-
DSPy is a framework from Stanford for programming language models rather than prompting them. You declare what each step should do, give it examples, and it writes and improves the prompts for you. ↩
-
TypeSafe’s launch post, Introducing System One Models and Jev, by founder Diogo Almeida, who worked on the research behind ChatGPT at OpenAI. Jev answers three kinds of question: a choice between up to 255 options you define, a score against a scale you describe, and a yes or no returned as a probability. Every answer comes with a calibrated confidence, so code can decide when to escalate to a person or to a bigger model. ↩
-
TypeSafe prices input at $0.042 per million tokens and charges nothing for output, with responses in 70 to 500 milliseconds. Its own comparisons use the average of Astra and Fable as the reference answer, which it admits favours those labs. Mike Taylor at Every ran an independent test: 777 judgements across 37 documents in under 0.7 seconds for about a quarter of a cent, and in a seeded check Jev caught six of seven planted defects where Fable caught all seven, at roughly 25 times the speed and a 580th of the cost. ↩
-
DeepSeek released V4.1 Flash on 10 September 2026 at $0.15 per million input tokens off-peak and $0.30 at peak, with output at $0.60 and $1.20. Gemini’s cheapest current Flash-Lite is $0.25 to $0.30 per million input tokens. Jev is $0.042 with output free. The one rate that undercuts Jev is DeepSeek’s cache-hit price of $0.003 per million, which only applies to a prompt prefix the API has seen recently. ↩
-
The Geek in Review has the clearest independent read on this. Its example: 10,000 documents at 95% confidence still means about 500 wrong answers nobody has flagged, and calibration degrades when the data drifts from what the model was trained on. Test the calibration on your own data before trusting it. ↩
-
The smart home assistant demo in TypeSafe’s documentation. The code asks every question at once rather than waiting for one answer before asking the next, splits a multi part request into atomic commands with an LLM, and delegates to a conversational model only for questions it cannot answer with a typed decision. ↩
-
The Qwen3 Reranker models judge whether a document meets a query and return the answer as the probability of “yes” read from the model’s own output layer, rather than as generated text. It is one question at a time and not calibrated the way TypeSafe claims, but the shape of the idea is the same. ↩
-
Latent Space’s AI News roundup, Here are 6 Clones of Jev in 2 days, lists Laya, DiffusionGemmaJev, Bespoke Nimble, SemIf (formerly OpenJev), Jevlike and Kev-0.5B, which is small enough to run on a MacBook. Bespoke Nimble, a fine-tune of Qwen3.5-9B, reports 90% on its own curated eval against 93% for Jev. Laya’s confidence scores are based on entropy and are not calibrated, and calibration is the property that makes a decision model useful as a router. ↩
High-res version available to newsletter subscribers